The Average That Picked the Wrong Courier
Two courier firms, one contract up for renewal, and a slide with two numbers on it.
The firms, the retailer and the deliveries are all made up, and the numbers are kept round so the arithmetic stays in plain sight. Swift and Steady each delivered 10,000 parcels last quarter, and the deliveries table behind the slide has just four rows:
import pandas as pd
d = pd.DataFrame({
    'courier':    ['Swift', 'Swift', 'Steady', 'Steady'],
    'route':      ['city', 'rural', 'city', 'rural'],
    'deliveries': [8000, 2000, 2000, 8000],
    'on_time':    [7200, 1200, 1900, 5200],
})
The slide took one groupby:
>>> tot = d.groupby('courier')[['deliveries', 'on_time']].sum()
>>> tot['rate'] = (tot['on_time'] / tot['deliveries']).round(3)
>>> tot
         deliveries  on_time  rate
courier
Steady        10000     7100  0.71
Swift         10000     8400  0.84
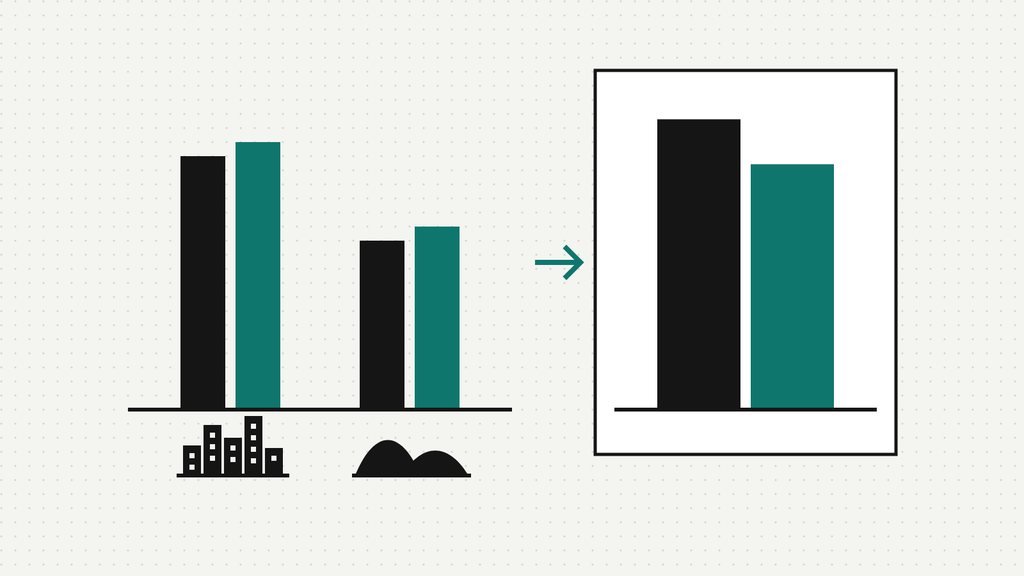
Swift got 84% of its parcels there on time and Steady 71%, and the recommendation at the bottom more or less wrote itself: renew Swift, let Steady go.
Thirteen points isn’t a rounding error, and with ten thousand parcels each it isn’t a fluke either: the gap is about 22 standard errors wide. The meeting was going to be short. Then someone asked the question that makes meetings long: on time doing what?
The column the slide left out
Deliveries aren’t all the same job. A city route is short hops between doorsteps. A rural one is half an hour of single-track lane between farms, stuck behind a tractor. Look back at the table: it had a route column all along, and the slide simply added the routes together. Work out the on-time rate for each road separately instead:
>>> d['rate'] = (d['on_time'] / d['deliveries']).round(3)
>>> rate = d.pivot(index='route', columns='courier', values='rate')
>>> rate
courier  Steady  Swift
route
city       0.95    0.9
rural      0.65    0.6
On city routes Steady was on time 95% of the time to Swift’s 90%. On rural routes, 65% to 60%. Steady is five points better on one kind of road and five points better on the only other kind there is. Neither gap is noise: the city one is about eight standard errors wide, and the rural one, where Swift has only 2,000 parcels, still about four.
Better in the city. Better in the country.
Worse overall.
What an average is made of
So where did Steady’s lead go? Into the mix. An overall on-time rate isn’t a separate fact about a courier. It’s that courier’s route rates averaged together, weighted by how much of each kind of work it did. And the two firms did very different work:
>>> share = d.pivot(index='courier', columns='route', values='deliveries')
>>> share = share.div(share.sum(axis=1), axis=0)
>>> share
route    city  rural
courier
Steady    0.2    0.8
Swift     0.8    0.2
Four in five of Swift’s parcels went to the city, where nearly everything arrives on time. Four in five of Steady’s went down country lanes, where a lot doesn’t. Weight each courier’s route rates by its own mix and the slide comes straight back:
>>> for c in ['Swift', 'Steady']:
...     print(c, f"{(share.loc[c] * rate[c]).sum():.0%}")
...
Swift 84%
Steady 71%
Swift’s 84% is 0.8 × 90% plus 0.2 × 60%. Steady’s 71% is 0.2 × 95% plus 0.8 × 65%. Picture each courier’s overall rate as a point on the line between its worst road and its best: the mix decides where on that line the point lands. Swift’s was pulled towards the city. Steady’s was pulled towards the farms.
This has a name. Simpson’s paradox is an association between two things that appears, disappears or reverses when you split the population into groups. Karl Pearson and George Yule wrote about it in 1899 and 1903; it was a short 1951 paper by Simpson that later gave it his name. Its most famous outing is a 1975 study of graduate admissions at Berkeley. Men were admitted at a higher rate overall, but department by department the picture changed: of the 85 departments the authors examined, four looked biased against women and six against men, or, in their words, “about as many units appear to favor women as to favor men”. The overall gap came from where people applied: women applied more often to departments that were hard to get into.
And the slide’s numbers aren’t lies. If the question is “what share of our parcels arrived on time last quarter?”, the totals answer it perfectly. They just don’t answer “which courier is better at delivering?”, which is the question the slide was being used for.
A fair race runs on the same roads
To compare the couriers, give them the same work. We can’t rerun the quarter, but we can ask what each firm’s own route rates would add up to on the other firm’s mix of routes:
>>> for routes in ['Swift', 'Steady']:
...     swift = (share.loc[routes] * rate['Swift']).sum()
...     steady = (share.loc[routes] * rate['Steady']).sum()
...     print(f"on {routes}'s routes: Swift {swift:.0%}, Steady {steady:.0%}")
...
on Swift's routes: Swift 84%, Steady 89%
on Steady's routes: Swift 66%, Steady 71%
On Swift’s routes, Steady would have scored 89% to Swift’s 84%. On Steady’s routes, Swift would have managed 66% to Steady’s 71%. Whichever mix you choose, Steady comes out five points ahead, because it’s five points ahead on every road. That’s the whole trick: compare rates on a common mix, so the comparison is about how well each firm delivers and not about who was handed the easy jobs.
Should you always split, then?
Here’s the uncomfortable part. Splitting flipped the answer, which makes it tempting to decide that the split numbers are always the true ones. They aren’t. A significance test can tell you a gap is real; it can’t tell you which way of cutting the data explains it. The computer scientist Judea Pearl argues that the numbers alone can’t tell you whether to split. It depends on how they came to be.
Route type is settled before a courier touches a parcel: the dispatcher assigns it, and it makes a delivery late or not all by itself. That’s exactly the kind of thing to hold constant. Now imagine splitting instead by whether a parcel needed a second delivery attempt. If a careless courier causes more second attempts, and second attempts cause lateness, then comparing couriers only among parcels with the same number of attempts hides part of the very carelessness you set out to measure. Same arithmetic, different question, wrong answer.
- Count the mix, not just the rate. How much of each kind of work is inside each number?
- If the mixes differ, compare like with like: split by the group, or recompute both rates on one common mix.
- Before you split, ask whether the grouping came before the thing you’re comparing, or because of it.
- Say which question each number answers. The total and the split can both be right.
The dataset here is invented. Every number above was computed by running the code shown, in pandas 3.0.5.
The next column along
Split by route and Steady wins. Split by route and season, or route and parcel size, and the lead might hold, or shrink, or flip back again. There is always another column, and any one of them could tell a different story.
The data can’t say which split is the last one worth making. That knowledge lives with whoever understands how parcels actually end up late: the dispatcher, the drivers, the person who knows which lanes flood in February. Were any of them in the room when the slide was made?
References
- Grouped Descriptive Statistics (PlexPrep lesson) — weighted statistics and shares by group, with a quiz
- Correlation vs Causation Principles (PlexPrep lesson) — confounding, colliders and Simpson’s paradox, in Python
- EDA Checklist (PlexPrep cheat sheet) — “check mixes before ranking”, with quizzes
- groupby, merge and reshape (cheat sheet) — a whole-Union figure as a ratio of sums, and what averaging five countries’ rates gets wrong
- Charts that Tell the Truth (cheat sheet) — how the same data can mislead, and a checklist for every chart
- Stanford Encyclopedia of Philosophy: Simpson’s Paradox — the definition, its history from Pearson and Yule to Simpson, the Berkeley example, and Pearl’s causal view
- Judea Pearl, Understanding Simpson’s Paradox (UCLA technical report R-414) — why the causal story, not the numbers, decides which table to trust; later in The American Statistician
- Bickel, Hammel and O’Connell, Sex Bias in Graduate Admissions: Data from Berkeley (Science, 1975) — the original study: 85 departments, four apparently biased against women and six against men
Related essays
▱
Python
|
▱
pandas
|
▱
Data quality
|
Comments
No comments yet. Be the first to share your thoughts.